Contributions
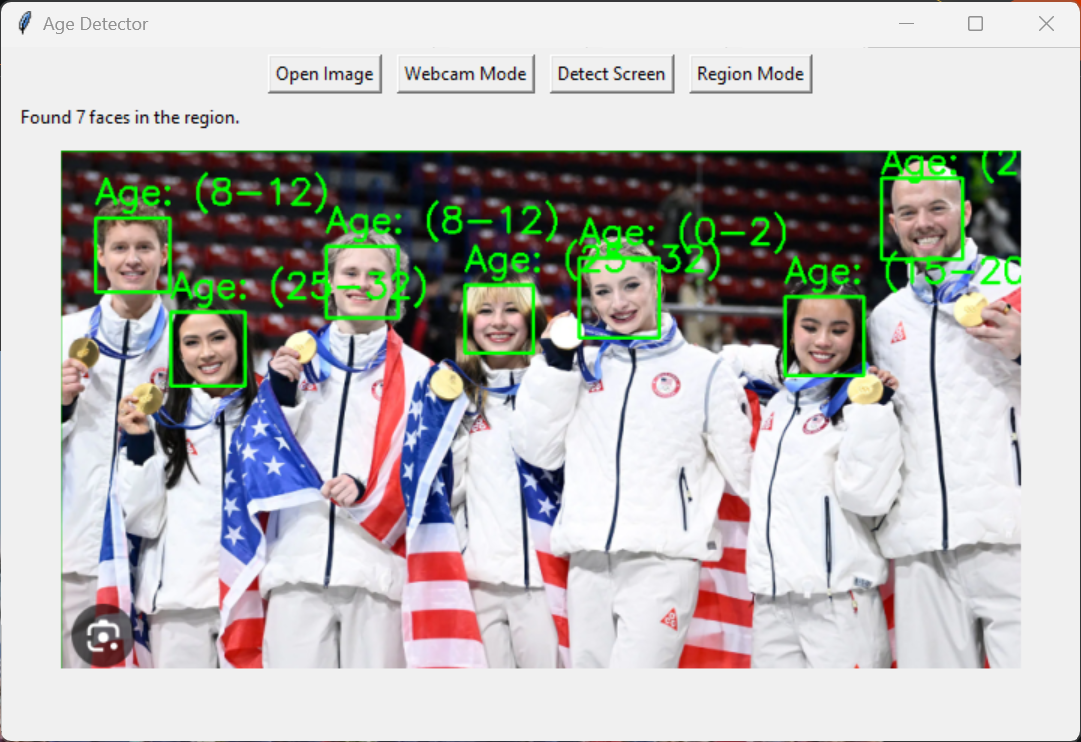
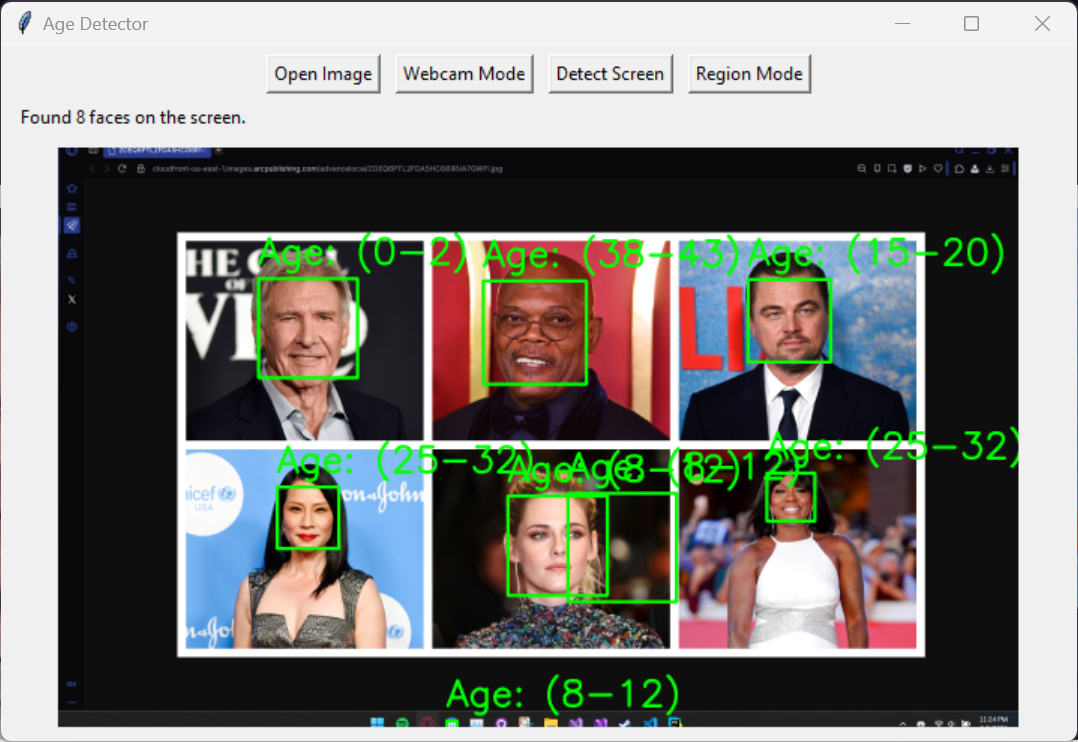
Face detection with age bracket prediction
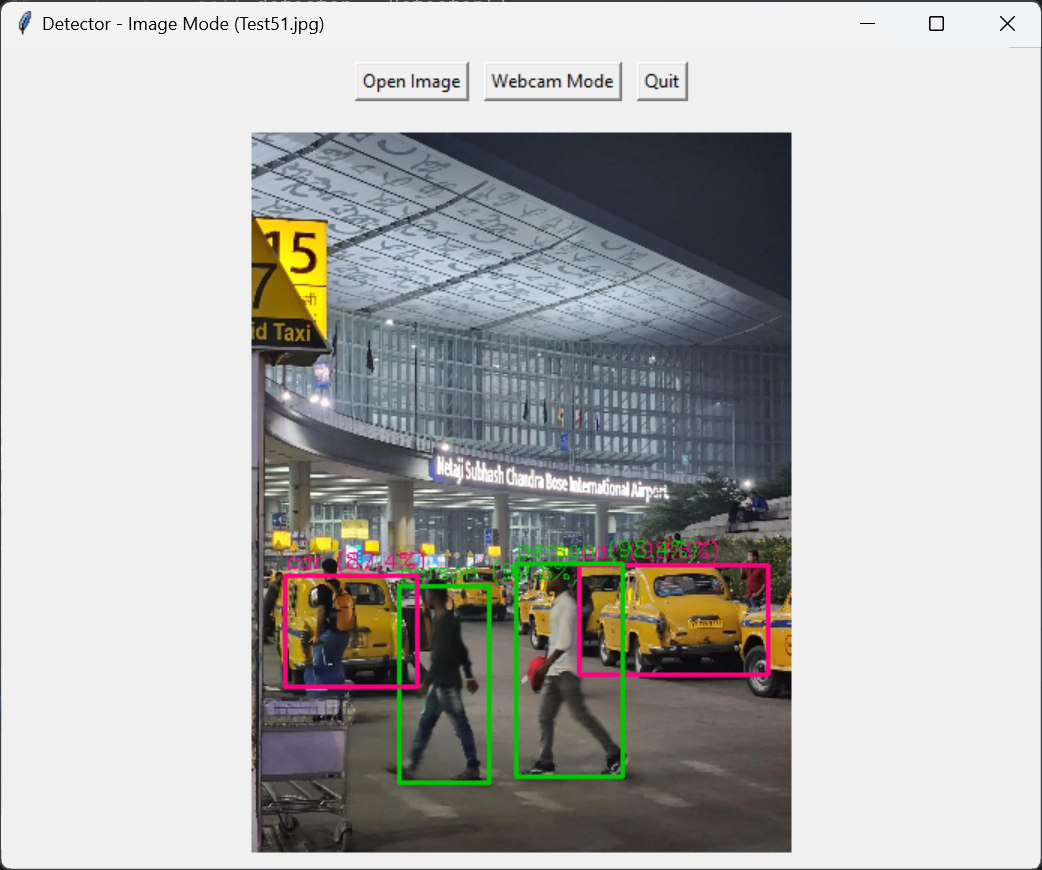
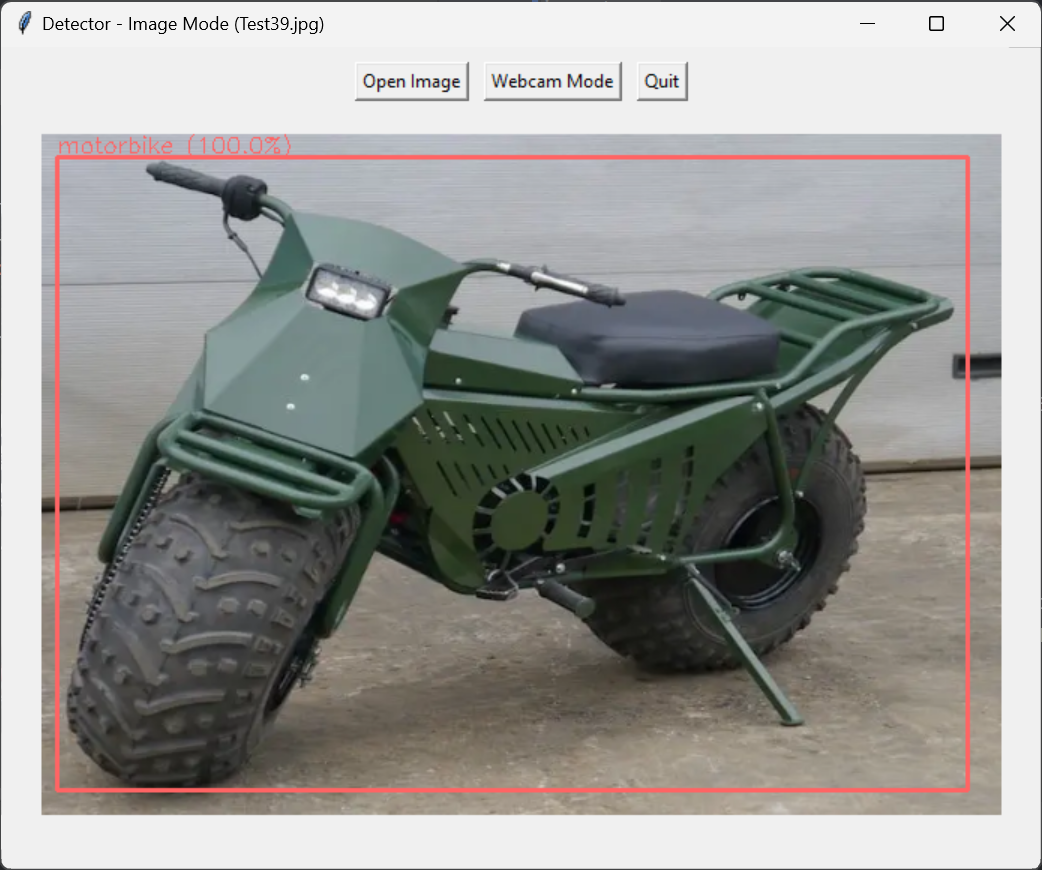
Object detection with confidence scores
Screen and region capture modes
Live webcam and image file input
Colour coding per detected class
Running count of what was found
Age Detection
- Faces get boxed and labelled with an age bracket rather than a single number, since that is what the model actually predicts.
- A status line reports how many faces were found, which makes it obvious when the detector misses someone.
- Four ways in: an image file, a live webcam feed, the whole screen, or a region dragged out by hand.
Object Detection
- A separate image mode labels objects with a class name and a confidence score.
- Detection is limited to a defined list of classes, so anything outside it is ignored rather than guessed at.
Crowded Scenes
- Each class draws in its own colour, so people and vehicles stay separable when boxes overlap.
- Busy frames are where the confidence score earns its place, since it shows which detections to trust.
Seven faces found inside a hand-drawn region.
Eight faces found by capturing the screen directly.
A single object, matched at full confidence.
People and vehicles picked out of a busy airport frame.